Course log · Part IIPatrol Lab · 2026-09-24 → 10-03Isaac Sim 6.1 · Isaac Lab 3.0 · Ubuntu 26.04

Blackforge
Robot Lab

A security-patrol robot in a simulated yard, a crowd of people who don't look where they're going, and an avoidance bake-off that turned out to be measuring the wrong thing. Then reinforcement learning, run the honest way: pre-registered, on sealed test seeds, until a learned policy matched the hand-written planner. Each lesson keeps a collapsed block that gives a coding agent what it needs to reproduce the step.

Module numbers follow the full course. Part I (teaching an SO-101 arm to put a mug in a bowl) is being redone with NVIDIA GR00T N1.7; the first two nights are below, and the full Part I follows. Reference code: github.com/matlowai/robot-lab-public. The talk version, with the opening reel, slides and an interactive field guide: talk. A side quest, turning one image into a 3D Gaussian splat with a video model: Splat Lab.

Modules
  1. I · It never let go
  2. 9 · Evaluated first
  3. 10 · Avoiding people
  4. 11 · The editor died
  5. 12 · An honest bake-off
  6. 15 · Teaching it to yield
  7. 16 · Up next
  8. ★ Gotchas
The bake-off: the same crowd, seed 21, three ways of avoiding people.
10/10
Randomised patrols, every incident caught
~50
Closed-loop people per crowd
94% → 6.6%
Hunter hits, no avoidance → planner
26.0 / 80
Bystander bumps, constrained RL (planner 27)
~15%
Hunter hits, constrained RL (planner 38.5%)
80
Sealed test seeds, run once
I

The arm, redone: it grasped, but never let go

Part I's SO-101 arm (put an object in a bowl, Isaac Lab 3.0) moves from FLUX 3 Action to NVIDIA GR00T N1.7. Two nights: the first model grasped and lifted but never opened its hand, and the cause was in the demos, not the model. All numbers are simulation, strict successes, with their denominators. GR00T rollout clips are treated as non-commercial (media license). 2026-10-04 → 10-06.

Lesson I.1

Swap the model, keep the test

FLUX 3 Action's weights are non-commercial, and on our task it scored 0 real successes: every success its detector reported overnight was fake. We replaced it with NVIDIA's GR00T N1.7 (3B parameters), which has an official SO-101 / LeRobot fine-tuning path. Its model card says NVIDIA Open Model License, but the LICENSE file shipped with the checkpoint is the non-commercial NVIDIA License; check which applies before any commercial use. The eval did not change: same objects, same seeds, same strict rule.

  • Strict success = the task's success term fires and the object was lifted at least 3 cm and the bowl stayed upright (≤ 20°) within 3 cm of where it started and no physics blow-up. Layouts with the object starting within 10 cm of the bowl are re-seeded.
  • Check the harness first. Recorded expert demos replayed through the same eval path: 31 of 32 strict on night 2. If that number were low, every policy number would be suspect.
  • Faster to plan: about 120 ms per action chunk against 0.9–1.2 s for FLUX.
Lesson I.2

It never saw itself let go

Night 1 fine-tuned GR00T for 25,000 steps on the 909 demos from the FLUX era. Final: 8/72 strict (12 episodes per object). Lifting worked: the blue block was lifted in 10 of 12 episodes. But in 48 of the 59 episodes where the object was lifted and not placed, the policy never commanded the gripper open at all.

The cause was the demo recorder. The environment reset the instant the object landed in the bowl, so each demo held about one release frame in roughly 145. And the last label of every demo was the reset pose, not the release. No amount of training teaches a behaviour that is missing from the data.

Night 1Night 2Same layout, seed 1004. Scene camera left, wrist camera right. Night 1 carries the block over the bowl and holds it there for the full 20 s. Night 2 opens and the episode ends on success at 4.4 s (its last frame is held).

Lesson I.3

Record the release, then weight it

Night 2 fixed the recorder: labels are read before the reset, and each kept demo includes a 0.5–1.3 s tail of release, retreat and settle. That gave 862 demos with a median of 42 release frames each. The fine-tune put a 5× loss weight on frames where the gripper opens or closes, from the base model, same recipe, 25,000 steps. Evaluation doubled to 24 episodes per object.

ObjectSplitNight 1 finalNight 2 final
Mugtrain5/1220/24
Soup cantrain3/1219/24
Blue blocktrain0/1217/24
Sugar boxtrain0/125/24
Cracker boxheld out0/125/24
Mustard bottleheld out0/127/24
All8/7273/144
  • Training objects 61/96, held-out objects 12/48. The held-out pair was never in the demos.
  • Weighting is a blunt tool. At the halfway checkpoint the 5× weight had overshot: on the blue block the gripper was commanded open most of the time and the policy lifted in only 1 of 12 episodes (halfway total 17/96). The final checkpoint recovered both grasp and release.
  • Look at every success. The report links a frame strip for each one; look at them before quoting a number.
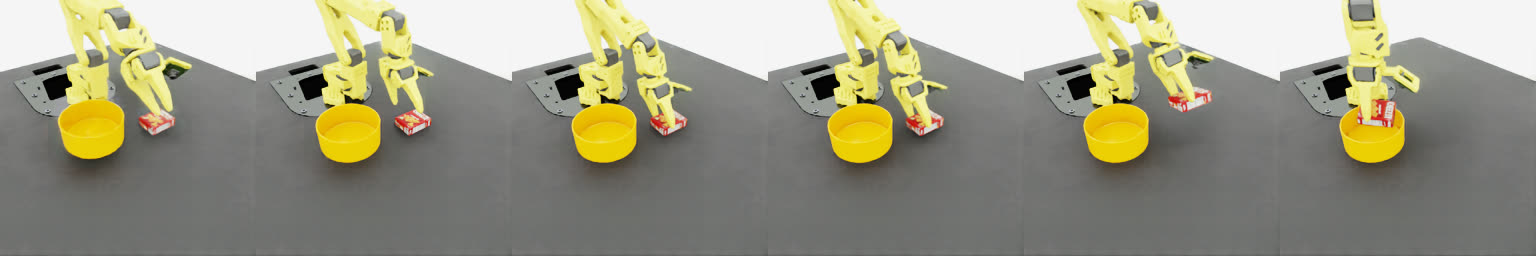
Held outCracker box, never in the training demos: grasp, carry, release in the bowl.
Six-frame strip of the cracker box episode from start to placed
The strip the report attaches to that success.
Reproduce with a coding agentcommands
cd /mnt/work/AI/robot-lab                       # code: code/robot-lab/tools in this repo
bash tools/overnight_gr00t_v2.sh tiny            # gate: every stage on a few demos, minutes
bash tools/overnight_gr00t_v2.sh full            # record -> convert -> fine-tune -> strict eval -> report
# output: overnight-gr00t-v2/full-*/MORNING_REPORT.md, eval/*/results_*.json, *_strict_strip.png
Agent prompt
The policy grasps and lifts but never opens the gripper. Before touching the model, count release frames per demo. Fix the recorder so it reads each step's label before any auto-reset and keeps a release + retreat + settle tail after success. Re-record, convert to GR00T's LeRobot layout, replay a few recorded demos through the strict eval (expect nearly all strict), then fine-tune from the base model with extra loss weight on gripper open/close frames. Evaluate on fixed per-episode seeds with the strict rule, and attach a frame strip to every success.

Lesson I.4

Can a local VLM tell whether it worked?

After an attempt, we asked a local vision-language model "is the object in the bowl?" and scored its answers against the simulator's ground truth. Frames taken at the instant of release are ambiguous, with the fingers still around the object: Gemma 4 12B missed 24–40 of 45 real successes there. So the arm retreats and waits about a second before the picture is taken.

Model (served locally)AccuracyFalse "done"MissedLatency
Gemma 4 12B94.7%5/500/450.64 s
Qwen 3.8 27B97.9%1/501/451.9 s

Then a 4-bit QLoRA fine-tune of Gemma (Unsloth, one epoch, 7,614 labelled frames mined from our recordings, one training seed per arm). It fixed the error we trained against and created another:

Same eval harnessBaseLanguage LoRA+ vision LoRA
Settled frames: false "done"12/503/502/50
Release-instant frames: missed successes15/4541/4543/45
Unseen objects: missed successes3/129/1212/12
  • Not deployable yet. The tuned models answer "the gripper is still closed" when it has just opened around an object already in the bowl. Our training frames had 805 "hovering over the bowl" failures against 117 release-instant successes; that imbalance is the leading hypothesis, untested.
  • Two harnesses, two baselines. The first table is the served models (Gemma on vLLM, Qwen on NInfer); the second is the fine-tuning harness (Transformers). Compare within a table, not across.
  • Code: code/robot-lab/verifier (frame builder, QLoRA training, eval against sim truth).

Lesson I.5

Or learn when to let go

The other route keeps night 1's model, the one that grasps but never releases, frozen, and trains a small PPO policy on top of it with residual reinforcement learning. Every action chunk, the policy adds a correction of at most 4° to the arm and decides whether to open the gripper now. Reward comes from the same strict checks. About five hours of training on one GPU, 185 waves of 64 parallel environments; two of 34 training rounds crashed (an environment ended during its settle step) and were skipped.

Then a paired test on sealed seeds never used in training: for each layout, GR00T alone and GR00T with the gate see the same scene and the same model noise.

ObjectSplitGR00T alone+ release gate
Mugtrain23/116113/116
Blue blocktrain14/116103/116
Soup cantrain17/121104/121
Sugar boxtrain4/11262/112
Mustard bottleheld out7/12176/121
Cracker boxheld out15/11546/115
Training objects58/465 (12%)382/465 (82%)
Held-out objects22/236 (9%)122/236 (52%)
  • Read it as "GR00T + release gate", not "GR00T learned to release": the gate is a separate learned policy, and the opening itself is a fixed jaw-open action.
  • Not comparable to night 2's 73/144: different seeds, and the gate sits on night 1's model. The gate has not been tried on night 2's model yet.
  • Look at the strips. We watched gated successes on the blue block and the held-out cracker box (in the bowl, gripper open) and a base failure that holds the box over the bowl.
AloneSealed layout, cracker box (held out). Night 1's GR00T carries it to the bowl and holds on.
+ gateSame layout, same GR00T noise, with the release gate: it lets go over the bowl.
Reproduce with a coding agentcommands
cd /mnt/work/AI/robot-lab/rl                    # code: code/robot-lab/rl in this repo
/mnt/weights/ai/isaac/IsaacLab/.venv/bin/python tests/test_core.py   # CPU tests
RUN=/mnt/weights/ai/robot-lab-data/gr00t-rl/runs/<name> GR00T_CKPT=<checkpoint> \
  TRAIN_END=$(date -d '+5 hours' +%s) GPU=1 bash scripts/run_rl.sh   # train, sealed eval, REPORT.md
Agent prompt
Freeze the imitation policy. Train a small PPO actor that, each action chunk, adds a bounded joint correction (a few degrees) and a Bernoulli "release now" decision; reward reach, lift, carry over the bowl, release inside the bowl footprint and the strict success, and penalise knocking the bowl. Batch many environments per object. Keep training, development and sealed evaluation seed ranges disjoint and assert it in code. Evaluate paired: base and base+residual on identical layouts and identical policy noise, with videos and strips.
9

A patrol robot, evaluated first

Spot walks a compound on NVIDIA's pretrained legs while staged incidents happen around it. The scorer existed before the robot did.

Lesson 9.1

Build the scorer before the thing it scores

Milestone M0 had no simulator at all: event rules (perimeter crossing, restricted zone, a fall, a vehicle in the wrong place, a gate left open, an obstacle on the route), a scorer, and scenario files that stage those incidents at known times. Only then did Isaac Sim join, in M1: Spot on NVIDIA's pretrained walking policy, walking a generated compound, with the rules reading facts back from the simulated stage.

  • Ground truth comes from what the scenario staged, never from what the rules detected. Scoring rules against their own output always gives 100%, so the scorer refuses rule output as truth, and a test checks that.
  • Test that the tester can fail. Drop a staged incident, add a phantom one, shift the times: the scorer must report each.
  • The M1 gate: both base scenarios pass in Isaac (all six incident types, 0 false alerts, full coverage), then 10 of 10 randomised variants, with every actor's timing shifted and its staged truth shifted with it.
M1 in Isaac. Overview left, chase camera right, and a burned-in status bar with the clock, task and incident log, so the evidence can be checked by eye.
Reproduce with a coding agentcommands
cd /mnt/work/AI/patrol-lab          # private: github.com/matlowai/patrol-lab
uv sync; uv run pytest -q           # rules, scorer, scenarios, planner (no GPU)
uv run python tools/run_scenario.py scenarios/library/SCN-M0-001.yaml --validate
CUDA_VISIBLE_DEVICES=0 OMNI_KIT_ACCEPT_EULA=YES /mnt/weights/ai/isaac/IsaacLab/.venv/bin/python \
  tools/run_scenario_isaac.py scenarios/library/SCN-M0-001.yaml --video
Agent prompt
Before any simulator: write event rules over a per-frame fact stream (tracks, zones, asset states), a scorer that matches detected incidents to incidents staged in a scenario file within a tolerance, and mutation tests that prove the scorer fails when an incident is dropped, invented or shifted. Then drive the same rules from Isaac Sim by rebuilding each 10 Hz frame from the stage itself (prim poses, gate hinge angles), never from the scenario file.
10

Avoiding people it can't predict

A simulated lidar, a hand-written local planner, and book readers who walk straight at the robot.

Lesson 10.1

An avoidance result means nothing without a control

Spot got a PhysX ray-cast lidar and a dynamic-window planner: sense, track, predict, choose a velocity. Against six oblivious book readers it finished the patrol with no near misses. The number only counts because the control run, the same patrol with avoidance switched off, walked into three of them and was knocked over.

Every planner bug showed up first in a 2-D world with circles for people, which runs a whole patrol in seconds:

  • Stalling short of the goal: scoring progress at the end of a rollout punishes the final hop. Score the closest approach.
  • Getting run over: treating each scan as frozen makes a head-on walker look static. Track velocities across scans.
  • Flip-flopping left and right: equal scores flip every tick. Commit to a side for a few seconds.
  • Phantom motion on walls: grazing-angle lidar hits slide along a wall as you move. Trust velocities only from clusters.

What we learned

  • Learned legs plus hand-written avoidance is a legitimate hybrid. Know which part is which before saying "it did it on its own".
  • Debug the planner in the cheap world; spend Isaac time only on what the cheap world can't show, like falls.
11

The night the editor died

An overnight bake-off that lasted two minutes and took the editor with it.

Lesson 11.1

Long jobs get their own cgroup

The overnight plan said "keep 20 GB free". The launcher checked free memory, then started six Isaac processes in the same second, and a seventh smoke test was already running. Every check saw the same free memory. All of them were children of the coding session inside VS Code, so when memory pressure hit, systemd-oomd killed the whole VS Code scope: 59.5 GB, the editor, the session, the orchestrator and every run.

  • nohup doesn't help. The out-of-memory daemon acts on the whole scope, not the process.
  • The relaunch ran each job as its own memory-capped unit and started Isaac processes one at a time, 90 s apart, only with 29 GB free. It ran all day with RAM never below 20 GB free.
Reproduce with a coding agentpattern
systemd-run --user --unit=patrol-night --collect -p MemoryHigh=44G -p MemoryMax=50G \
  --working-directory=$PWD uv run python tools/overnight_patrol.py --stages s1,s2 --parallel 4
journalctl --user --since "-1h" | grep -i oom        # what oomd did, if anything
12

The bake-off gets honest

Hand-written planner against a reinforcement-learning policy, on the same crowds. The first answer was confounded, and a video showed it.

Lesson 12.1

Watch the video, not just the table

The RL policy looked "stuck" at the end of a three-way comparison video. It was parked: it had finished the patrol 40 seconds early. The book readers were keyframed to a timetable fitted to the no-avoidance robot, which stops and turns in place. The planner and RL turn while walking, ran 10–13% ahead, and outran their encounters. The "collisions" at the end were late readers walking into a robot that had already gone home.

Arrives atCrowd timetableNo avoidancePlannerRL
Checkpoint 151.5 s50.5 s46.7 s44.5 s
Checkpoint 4147.1 s144.4 s135.2 s128.7 s
Checkpoint 7273.3 s268.4 s249.7 s239.6 s
Home332.6 sfell at 295 s302.3 s292.4 s
ConfoundedSeed 21 finale. Left: no avoidance, down. Middle: the planner, parked, sandwiched by two late readers. Right: RL, parked a metre away and missed.

Lesson 12.2

Opponents that react to the thing under test

The fix was a closed-loop crowd of about 50 people: wanderers reading books, loiterers standing on the route, and hunters posted beside every patrol leg. A hunter sees Spot (range, vision cone, line of sight that buildings block), locks on, predicts where it's going and walks to intercept. Inside 2.5–4.5 m it commits to a straight line and stops re-aiming. A pursuer that re-aims until contact at walking speed can't be escaped, and then there's nothing to learn.

40 seeds, 2-D worldLock-ons per runHit per committed hunter
Base tier, no avoidance15.394%
Base tier, planner15.66.6%
Hard tier, no avoidance22.499.8%
Hard tier, planner23.839%

Both contenders now get the same exposure. The cheap world was then checked against Isaac on the same 8 seeds: 6.1% hits per commit in Isaac, 7.9% in 2-D. Isaac adds what 2-D can't express: 3 of the planner's 7 hits knocked Spot over.

EvadedThree hunters lock on at once (magenta bar). The planner slips through all three.
HitNo avoidance: the first committed hunter walks straight through Spot.
Reproduce with a coding agentbenchmark
cd /mnt/work/AI/patrol-lab
uv run python -m benchmarks.avoidance.sim2d --seeds 1-40 --controllers control,heuristic --workers 40 --live hard
uv run pytest -q tests/test_pedestrians.py     # commit rule: standing still is hit, a timely sidestep evades
Agent prompt
Write one closed-loop crowd model used by every consumer (2-D benchmark, Isaac runner, torch RL env): wanderers, loiterers and hunters posted beside each patrol leg. Hunters lock on when the robot is in range, inside a vision cone and not hidden by buildings; they aim at a constant-velocity intercept, re-aim every 0.5 s, and commit to a straight line inside commit_m. Score per lock (hit or evaded) and report lock-ons per run next to every hit rate. Port the hunter state machine to torch and prove parity with the numpy reference over a scripted robot path.

Lesson 12.3

Report the denominator

Hit-per-commit is conditional. A contender that's slower meets more hunters; one that falls early meets fewer; one that bumps ordinary people doesn't show up in it at all. On 80 held-out hard-tier seeds:

ControllerHunter hitsLock-ons / runRuns bumping ordinary peopleMedian patrol
Planner38.5%24.027/80377 s
RL, 2 lidar frames 0.1 s apart37.2%28.361/80462 s
RL, lidar at t, −0.3 s, −0.6 s35.2%23.955/80388 s

Longer lidar memory helped against hunters and made RL much faster, but RL still bumps ordinary people twice as often. Its training world had 4–8 people per scene; the benchmark has about 50.

Lesson 12.4

Privileged information leaks through the scene

Hunters had debug beacons that turned magenta when locked on. Spot's head camera, which records the training data for a vision policy, could see those beacons from about 4 m. The data would have told the model each hunter's hidden intent. Debug visuals are now invisible whenever the head camera records, and a check counts forbidden pixels: 0 in 600 frames that included 5 lock-ons.

What we learned

  • Scripted opponents must react to the thing under test, or a faster contender just outruns them.
  • Check a cheap simulator against the real one on the same seeds before trusting it.
  • Keep debug-only visuals on a layer the learner's sensors can't see, and test it by counting pixels.
15

Teaching it to yield

The learned policy dodged hunters but kept bumping ordinary walkers about twice as often as the hand-written planner. Six fixes failed. What worked was asking what the robot could actually perceive, then giving bystanders their own price. 2026-09-26 → 10-03.

Lesson 15.1

One change per arm, and a script that killed three runs

Contact forensics had shown that RL bumps people it had seen for about 3 seconds while it kept walking at full speed. Its forward-speed action had collapsed into a go/stop switch. So the next night ran four pre-registered arms, one change each. Checkpoints were picked on validation seeds, each pick ran once on 80 sealed seeds, and the win rule was written down before launch.

80 sealed seedsRuns bumping ordinary peopleHunter hitsMedian patrol
Planner (the bar)27/8038.5%377 s
Baseline51/8031.0%382 s
Speed channel fixed49/8028.4%368 s
+ time-to-collision penalty55/8031.0%377 s
+ warm start from a clone of the planner55/8023.2%352 s

The speed fix worked as a mechanism: the action came back to life, with 15% of steps at in-between speeds. But contacts didn't fall, so speed wasn't the bottleneck. Three of the arms almost didn't report at all. While they were running, I edited the shared launch script for the fourth. Bash reads a script lazily, so seven hours later they resumed at a shifted offset and died with unexpected EOF. A parse error skips the error trap, so their status said "running" forever.

What we learned

  • Pre-register the arms, the selection rule and the win rule before the run, so a "no" is still a clean answer.
  • A diagnostic passing (the speed channel is alive) is not the behaviour improving. Check both.
  • Never edit a script a running job is executing. Launch every long job from a frozen copy.

Lesson 15.2

Can a network even copy the planner?

Six 7-hour fixes had all changed the reward or the behaviour. None asked whether the policy's input contained the cue. The policy saw three lidar snapshots 0.3 s apart, and in that time a crossing walker moves less than one lidar sector. The cheap test is imitation: clone the planner from the candidate input, change nothing else, and see whether the copy yields. If imitation can't recover a behaviour from an input, RL almost certainly can't either.

Clone of the planner, 40 validation patrolsFirst copyDAgger 1DAgger 2DAgger 3
RL's input (lidar only)37363239
+ the planner tracker's velocity per direction17282322
+ velocities + the planner's chosen detour side15201323
The planner itself18

The missing ingredient was which way people are moving. The test cost 40 minutes of CPU. The planner's code was refactored to expose its tracker, and the change was checked by reproducing the 40 reference patrols row for row.

Reproduce with a coding agentclone probe
cd /mnt/work/AI/patrol-lab
systemd-run --user -p MemoryMax=26G --working-directory=$PWD env GPU= tools/clone_probe.sh avoid-v2t
Agent prompt
Before another RL run, test whether the policy's observation can express the expert's behaviour at all. Record the expert (our hand-written planner) driving sim2d patrols with the candidate observation, behaviour-clone it, run 3 DAgger rounds (the clone drives, the expert labels), and score round 3 (fixed in advance) on validation seeds only. Change only the observation between arms. Commit the reading rule first: what result means "the input is the bottleneck".

Lesson 15.3

Give it velocities, and check the emulation

The GPU training world can't run the real tracker, so it emulates it from the true positions. People must be hit by at least two rays, velocities are smoothed and only trusted from the third scan, and 0.2 m/s of noise is added. Before training, the real tracker was run on the training world's own scans and compared direction by direction: 98.5% agreement on what is moving, direction cosine 0.996. At deployment and in every score, the real tracker supplies the velocities.

80 sealed seedsRuns bumping ordinary peopleHunter hitsMedian patrol
Planner27/8038.5%377 s
Speed-fixed RL, no velocities49/8028.4%368 s
+ velocities, seed 042/8018.6%330 s
+ velocities, seed 140/8017.1%332 s
+ velocities, started from the velocity clone36/8015.8%331 s

Every arm improved, on every measure. It still wasn't the planner. The literature said the same: in DRL-VO, a policy with pedestrian velocity inputs but only distance penalties stayed below a hand-written planner until a predicted-conflict reward was added.

What we learned

  • Ask "can it perceive this?" before "how do I reward this?".
  • Information makes the right behaviour learnable. It doesn't make it worth learning.
  • When training emulates a sensor, measure the emulation against the real sensor on the same data, and evaluate through the real one.

Lesson 15.4

A separate price for bumping bystanders

One −10 contact penalty covered hunters and bystanders alike, and 7 of 8 training contacts were hunters. The best move against a hunter (keep speed, sidestep) is exactly wrong for someone crossing your path (slow down, let them go). So the reward stayed the same, and a separate cost was added for ordinary people only. It charges for driving into where each walker will be in the next few seconds, for closing speed when near, and for contact. Constrained RL (PPO-Lagrangian) gives the cost its own critic, and a multiplier that rises automatically until the cost is under budget. Nobody hand-tunes the weight.

How far ahead should it look? The question came from driving: you track cars 20 s out, and things that loom grab your attention. A 12 m lidar at walking speeds gives about 4–6 s of warning, so we tested 2 s against 5 s, with two training seeds each.

80 sealed seedsRuns bumping ordinary peopleHunter hitsMedian patrol
Planner27/80 (34%)38.5%377 s
Starting point (velocities)36/8015.8%331 s
+ bystander cost, looking 2 s ahead, seed 030/8014.3%332 s
+ bystander cost, looking 2 s ahead, seed 1Beats24/8013.9%332 s
+ bystander cost, looking 5 s ahead, seed 030/8016.6%341 s
+ bystander cost, looking 5 s ahead, seed 1Beats20/8015.1%335 s
All four bystander-cost runs104/320 (32.5%)≈15%≈335 s

In plain words: once it could see where people were heading and had a separate price for crowding bystanders, the learned robot bumped people about as often as the hand-written one. It dodged the people chasing it 2.5× better and finished patrols about 10% faster.

Two of four runs beat the planner on every criterion. The pre-registered demo pick (the best validation score, 5 s seed 0) did not, and naming a winner after seeing the test would be cherry-picking. 2 s versus 5 s couldn't be separated: the random seed moved results by 6–10 runs, as much as the look-ahead did.

What we learned

  • One shared penalty for different failures lets the common one set the price. Price each failure separately, and let a budget set the weight.
  • Penalise what's coming (predicted conflicts, closing speed), and only penalise what the learner can observe. The same time-to-collision idea failed before the policy could see velocities.
  • Look-ahead is a design parameter, set by sensor range ÷ closing speed. Looming (time to contact per direction) as an explicit input is the next experiment.
  • Replicate on a second training seed before comparing two variants.
Reproduce with a coding agentconstrained RL
cd /mnt/work/AI/patrol-lab
PYTHONPATH=. python -m benchmarks.avoidance.rl.train --out runs/L0 --hours 7 --preset hard-dense --obs avoid-v2t \
  --set w_space=0 --set track_noise_mps=0.2 --squash clip --log-std-max 0 --bound-coef 0.01 --lr 1e-4 \
  --init-ckpt <v5 V3 final> --init-critic --critic-warmup 100 --set ambient_cost=true \
  --set cost_horizon_steps=10 --set cost_dt=0.5 --set cost_decay=0.85 --cost-limit 0.0173 --seed 0
Agent prompt
Add a per-step cost that covers only the agents the benchmark scores as bystanders (never the adversaries). It should charge predicted intrusion into each one's constant-velocity path over a tunable horizon, closing speed inside 0.4 m, and contact. Report it in info["cost"] and never in the reward (test that rewards are bit-identical with it on). Train with PPO-Lagrangian: a separate cost critic, advantage (A_r − λA_c)/(1+λ), and λ updated from the rollout's mean cost against a limit set in advance at half the starting policy's cost.

Lesson 15.5

The winner's curse

Every RL run looked better on the 40 validation patrols than on the 80 sealed ones, and I first wrote that the sealed seeds were "harder for RL". They weren't. Each run kept the lowest of 14–18 checkpoint scores, and each score was a noisy estimate from 40 patrols. The minimum of many noisy numbers is mostly the luckiest one.

Runs bumping ordinary peopleValidation, picked checkpointValidation, all checkpointsSealed test
Lidar only (4 runs)42–55%56–73%61–69%
+ velocities (3 runs)28–32%47–51%45–52%
+ bystander cost (4 runs)18–25%31–32%25–38%

Averaged over checkpoints, validation matches the test. It even ranked the last runs backwards: the best-validation run tied worst on the sealed seeds. My first explanation leaned on one anecdote ("that pick was the last checkpoint, so it isn't selection"), and the statistic overturned it. The next protocol picks on far more patrols, or fixes the checkpoint in advance.

What we learned

  • Picking the best of many noisy scores flatters the pick. Use a much larger selection set, or a rule with no picking, and look at the average as well as the best.
  • Settle a suspicion with the statistic, not an example.
  • Ask whether a gap is distinguishable before calling it a win: 20 vs 27 of 80 is p ≈ 0.3. Pool replicates for the claim.

Lesson 15.6

Before you train a robot to share space with people

These are the questions that would have saved the most time, in order:

  1. Can the policy perceive the cue? List what a good human or a hand-written controller uses (here: which way each person is moving), and check it's in the input at the rate the decision needs. Test it by imitation before any RL.
  2. Does the reward price each failure separately? Chasers and bystanders need opposite responses. A shared penalty is set by whichever is more common.
  3. Does the signal arrive early enough to act on? Contact is too late. Predicted conflicts and closing speed arrive seconds earlier, while braking still helps.
  4. Does training contain the situation, as often as the robot meets it? Count what's near the learner, by kind, per step, not headcount per scene.
  5. Can the policy actually act? Watch the action distribution. A saturated output can turn "speed" into an on/off switch.
  6. Is the evaluation honest? Opponents that react to the contender, exposure reported beside rates, a control run, sealed seeds run once, enough data to pick checkpoints, more than one training seed, and the reading rule committed before you look.
  7. Will the pipeline tell you when it fails? Frozen launch copies, resumable stages, deadlines with fallbacks, memory caps, and no status that can say "running" forever.
16

Up next

Part II's next lessons, written when they happen.

  • RL avoidance: pick checkpoints on far more validation patrols (or fix the pick in advance), add training seeds to settle 2 s versus 5 s look-ahead, then try looming (time to contact per direction) as an explicit input.
  • The safety-shield hybrid: 20/80 bystander bumps, but it finished one patrol too few. Make the shield check whether the fallback can still recover, add hysteresis, and log why each patrol failed.
★

Gotchas

Quaternions are xyzwIsaac Lab 3.0 uses x, y, z, w. A 90° yaw is (0, 0, 0.707, 0.707).
ProxyArray, not tensorsSim data fields are Warp-backed. Call .torch before TorchScript math like quat_apply.
Instanced assets ignore overridesMass settings silently don't apply. Use startup events (friction via randomize_rigid_body_material).
Stale first frameThe first render after a reset is old. Drop the first frames of every episode.
libxml2 on Ubuntu 26.04Only libxml2.so.16 exists, which breaks FBX/OBJ import. URDF/MJCF importers bundle their own converters.
Don't kill yourselfpkill -f pattern can match the shell running it. Anchor the pattern to the interpreter path.
Soft gripper defaultThe SO-101 IK task caps grip torque at 1 N·m for cubes. We use 3 N·m.
Success detectors lieOurs counted a bowl flung through the table as a success. Watch every "success" episode before reporting a number.
One seed, one bad layoutA fixed eval seed replays the same broken reset for every policy. Seed per episode.
Match the start stateDemos began with the jaw at 16; eval began at 9. The policy kept the jaw shut for 20 s.
Chained background jobsWaiting on log markers spawned duplicate runs twice. Wait on process IDs instead.
nohup won't save yousystemd-oomd kills a whole scope. Run long jobs as their own systemd-run --user -p MemoryMax=… units.
Free-RAM checks raceSix launches that check free memory in the same second all see the same number. Launch one at a time, after the last one has grown.
Never edit a running scriptBash reads scripts lazily. An edit made while a job runs it can kill the job hours later with a parse error that skips the ERR trap. Launch from a frozen copy.
The best checkpoint is the luckiestThe minimum of 14 noisy 40-episode scores looked 10–20 points better than the test. Select on far more episodes, or not at all.
Scene-data arrays go staleIsaac Lab reallocates transform buffers on hard reset. Re-read every frame; never cache the array.